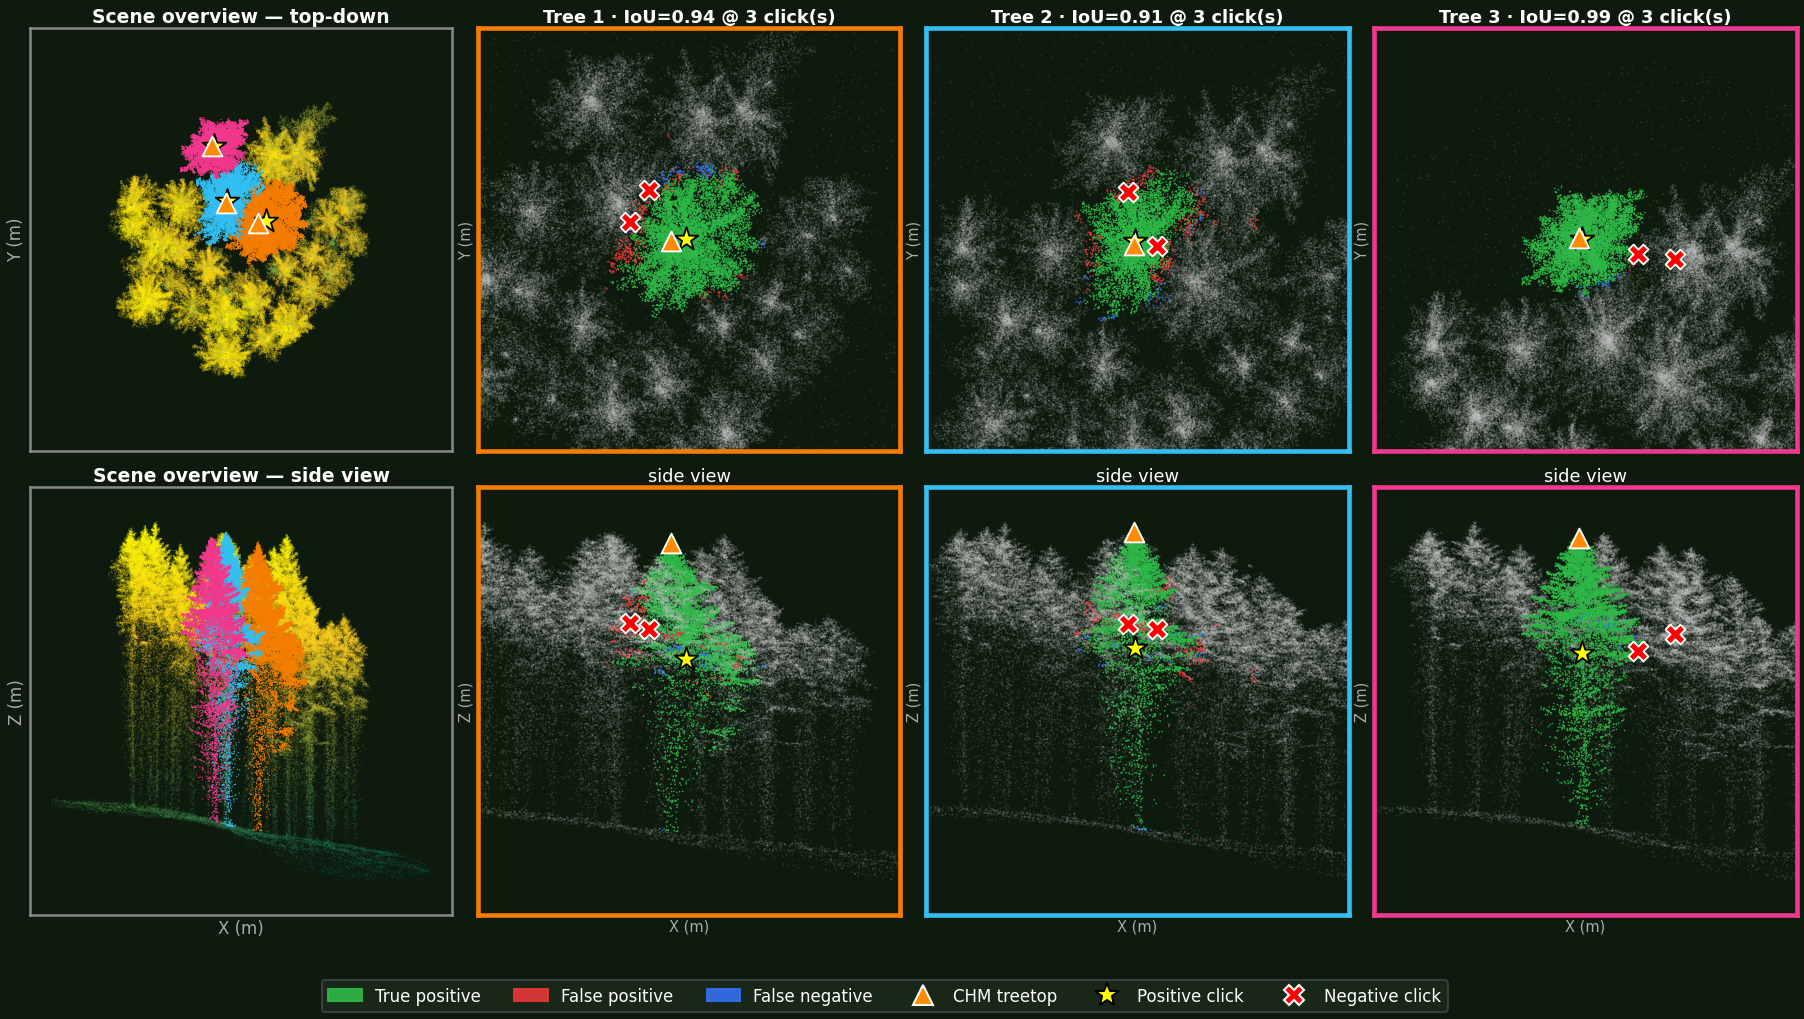
Instance segmentation of trees in forest LiDAR point clouds is constrained by label scarcity: a single hectare holds millions of points and hundreds of overlapping tree crowns, making manual annotation laborious, while automatic pre-segmentations offer no interactive refinement.
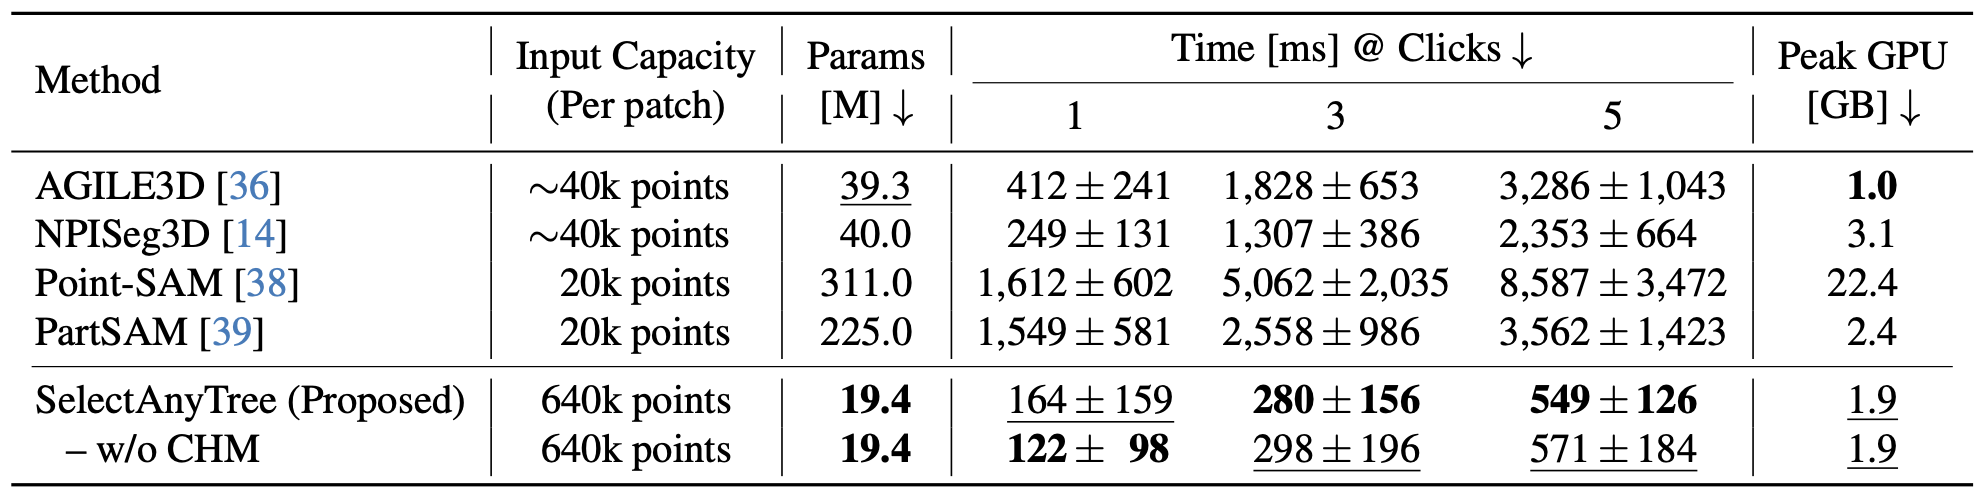
Inspired by the promptable paradigm of foundation segmentation models, we propose SelectAnyTree, a promptable instance segmentation model that delineates any individual tree in a 3D forest point cloud from a few clicks. It couples three lightweight stages: (1) a sparse voxel scene encoder that embeds the forest once into reusable features; (2) a click-to-query prompt encoder that turns each click into a single content query from its 3D position, positive/negative polarity, and the backbone feature of its nearest voxel; and (3) a state-space query decoder that converts this query into one tree mask in linear time, with a mask feedback that conditions each refinement round on the previous mask. Each additional tree costs only a lightweight prompt-encoding and decoding pass, and the full model uses just 19.4M parameters — far fewer than prior promptable 3D models. We further exploit forest-aware geometry by detecting treetops as local maxima of the Canopy Height Model (CHM) and associating one with the user's click as a free initial prompt.
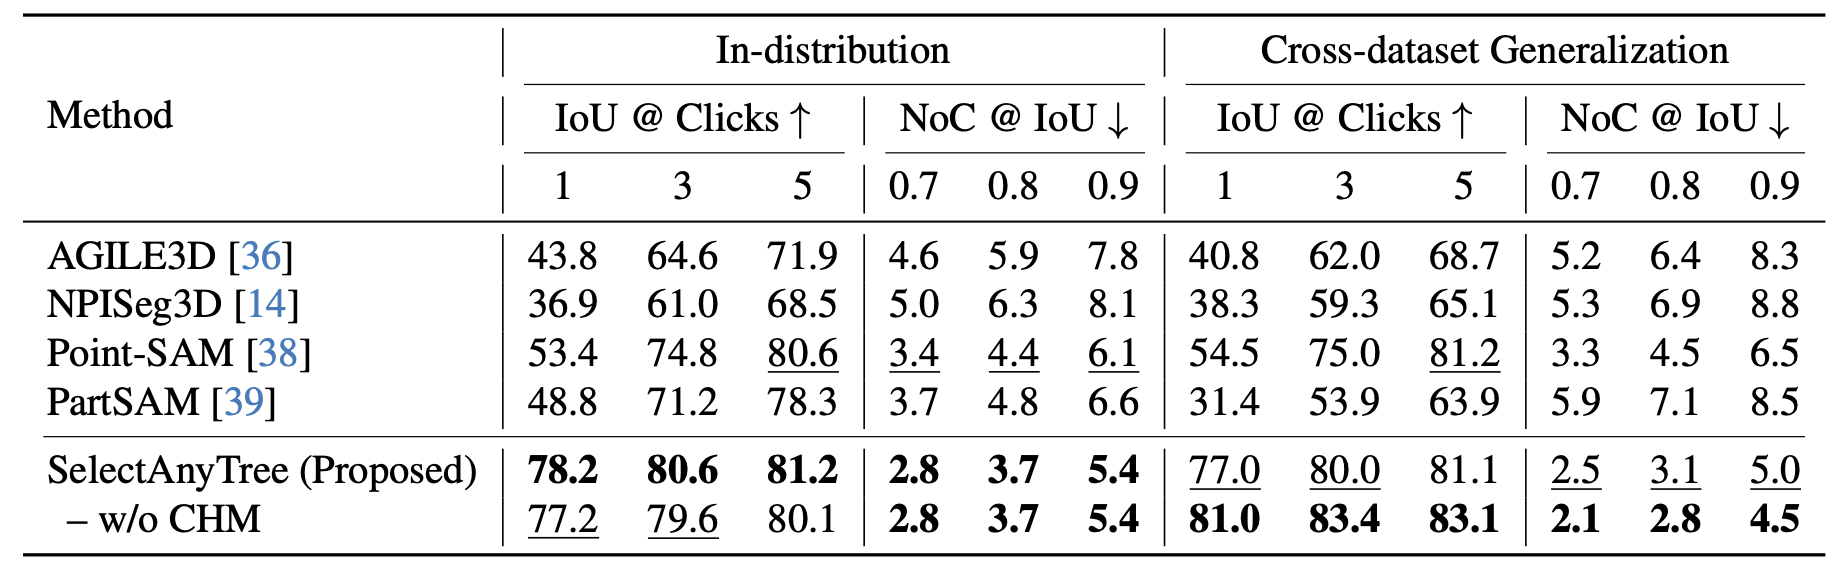
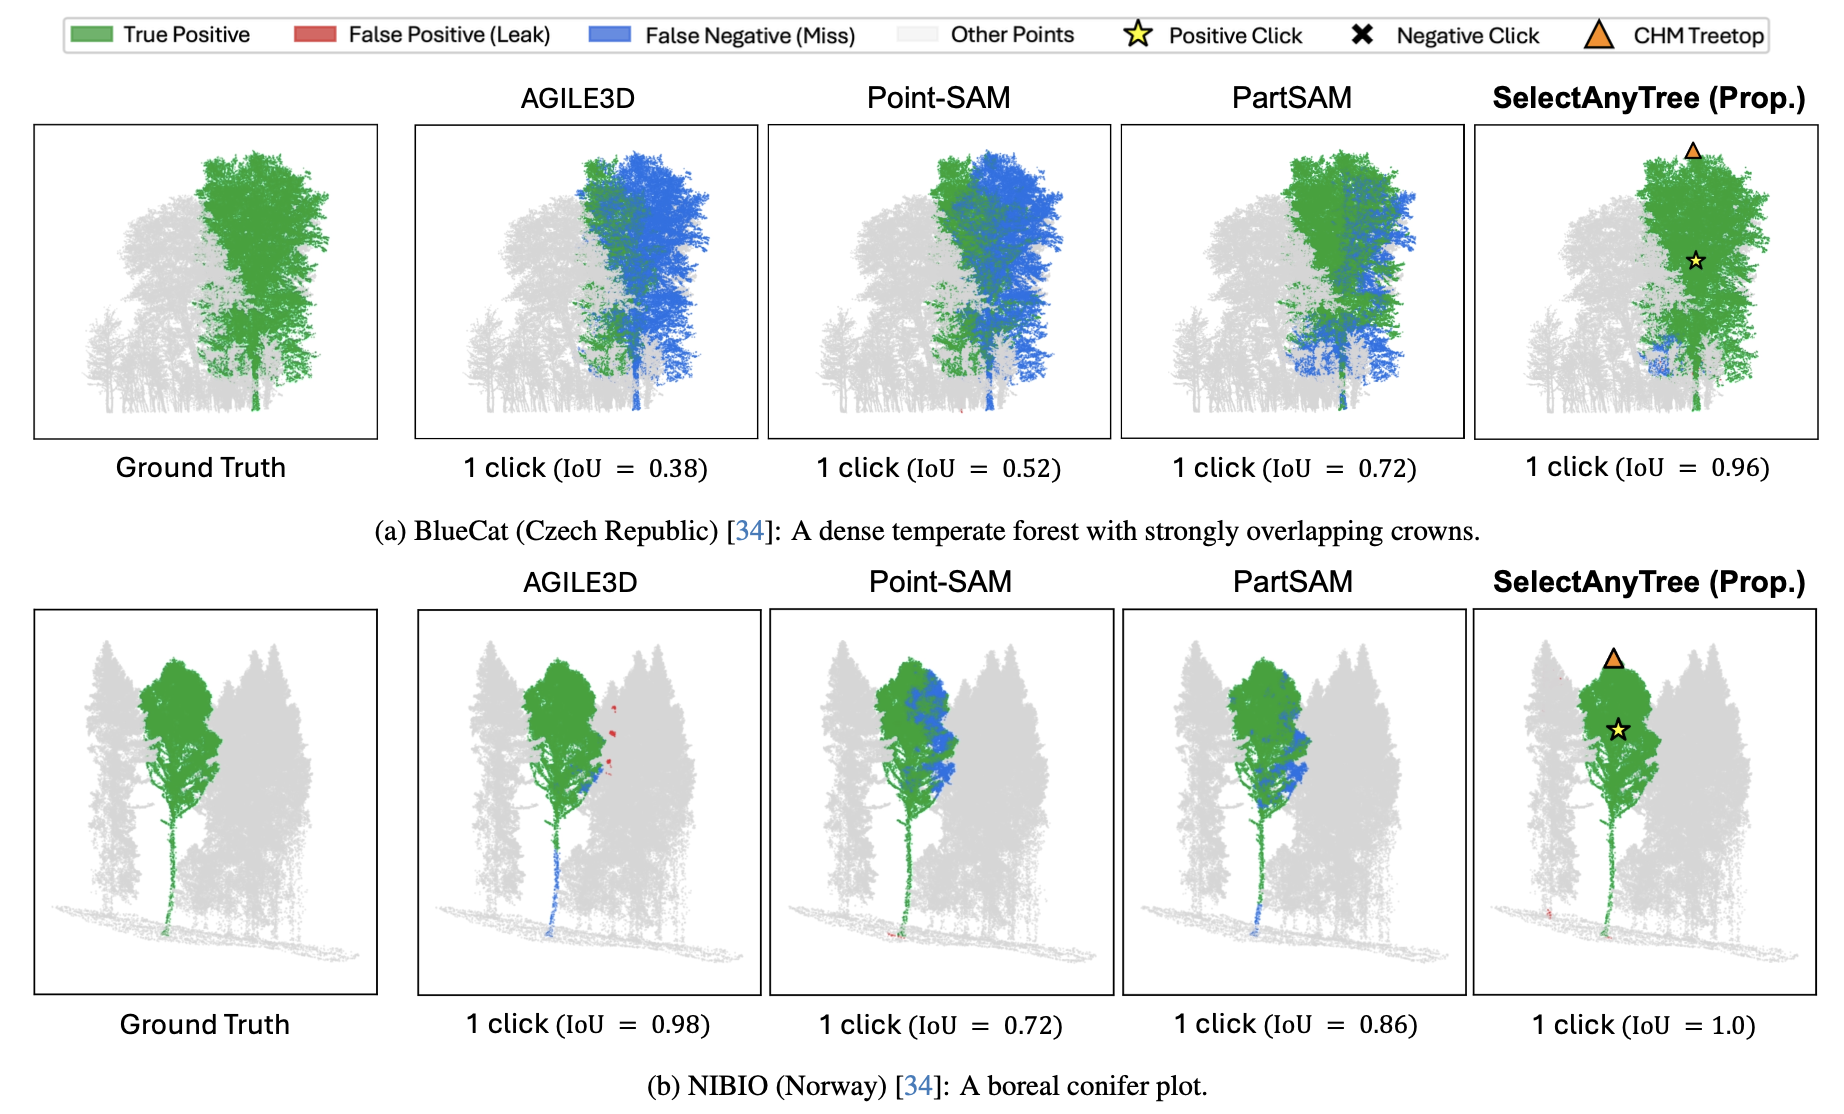
Across seven diverse forest regions and an independent held-out dataset, SelectAnyTree segments a target tree to 79.9 IoU from a single click — 24.7 points above the strongest promptable baseline — and reaches every accuracy target with the fewest clicks.
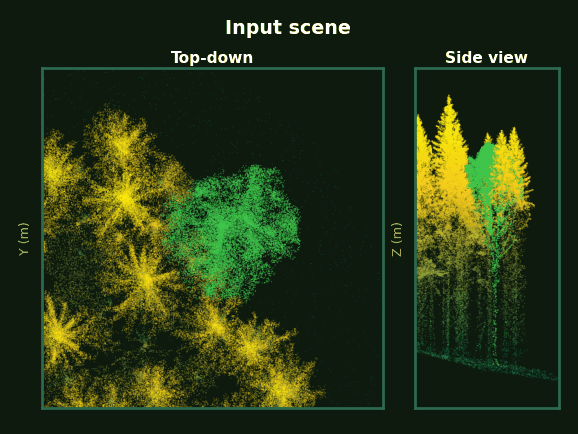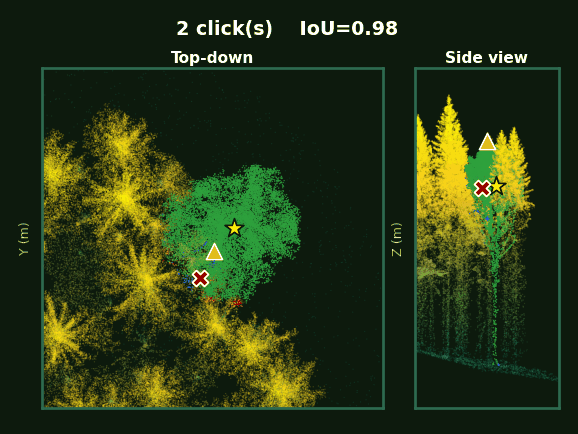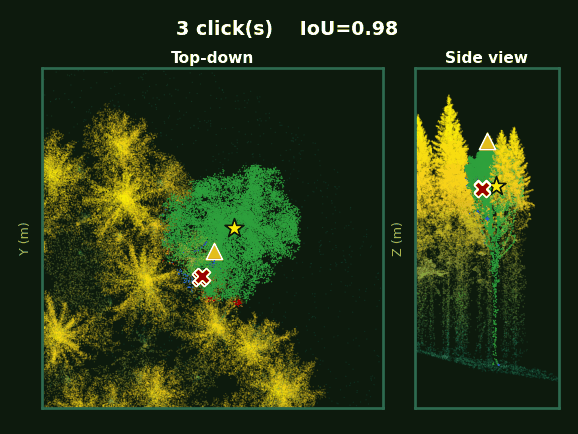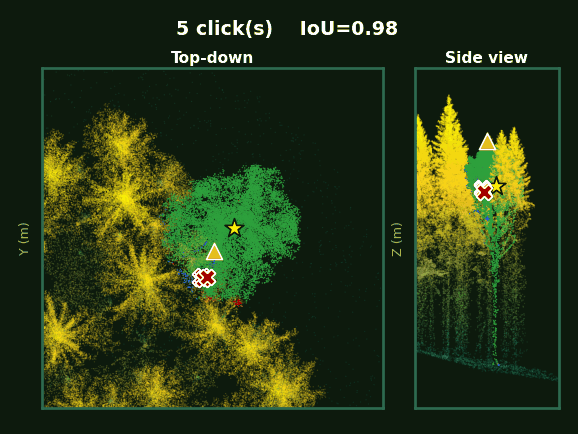
Pre-computed from the test set. Each frame shows top-down view (left) and side view (right).
Left: the whole plot with every tree segmented. Right: each tree, rotating, as prompts accumulate from 1 to 5 clicks.
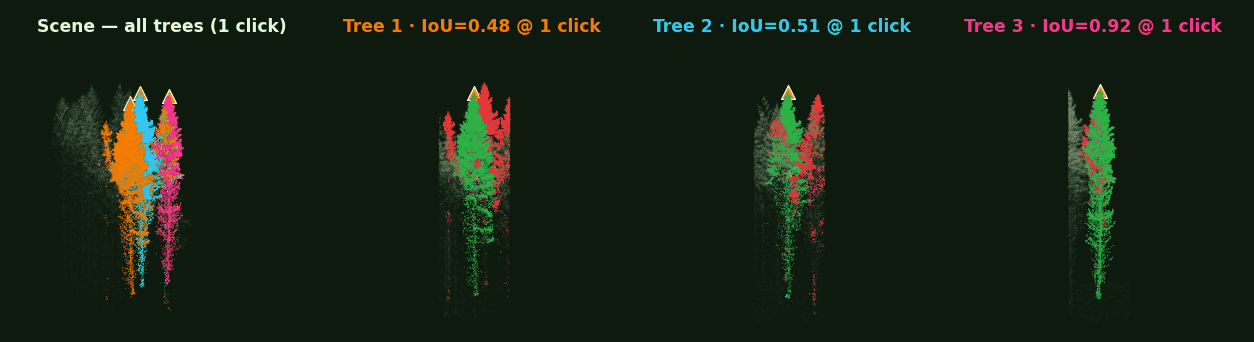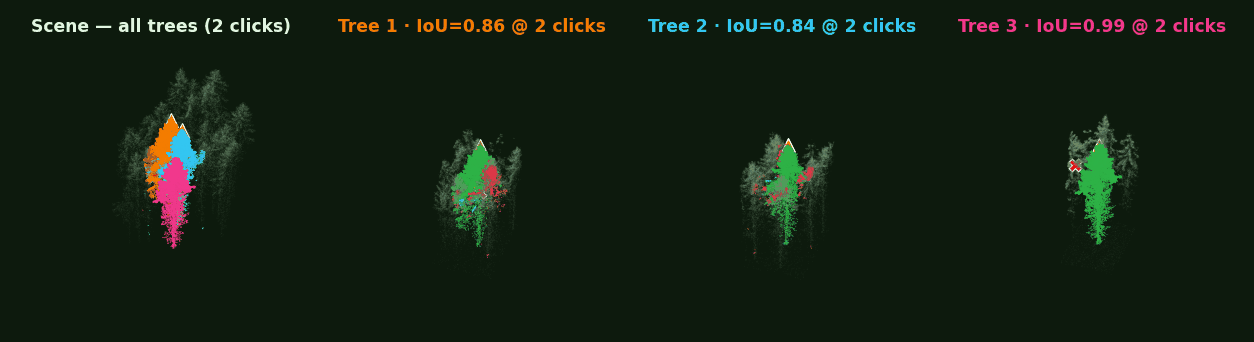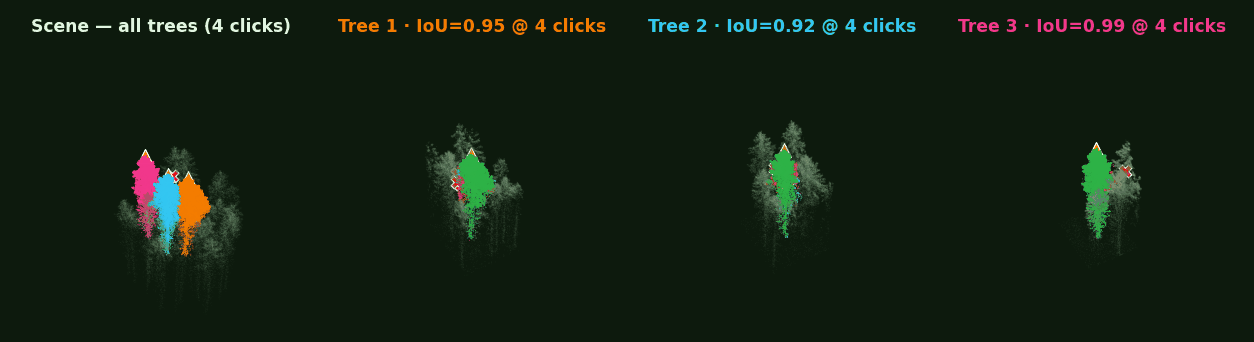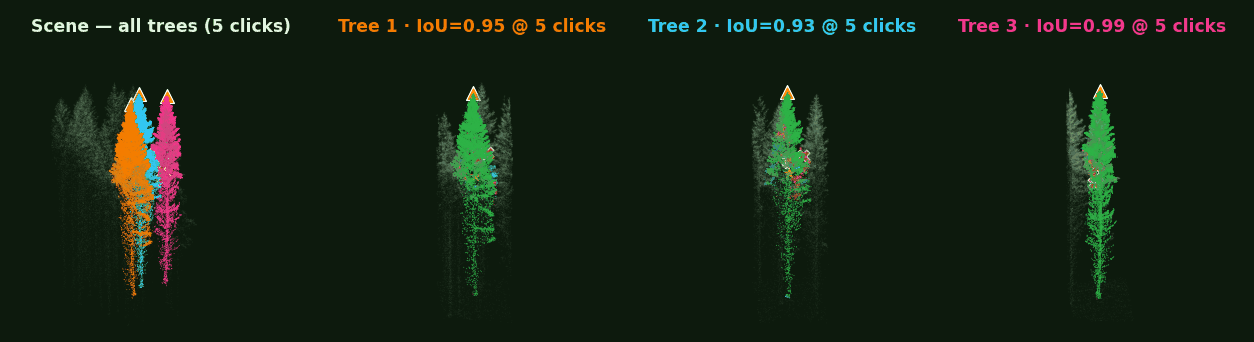
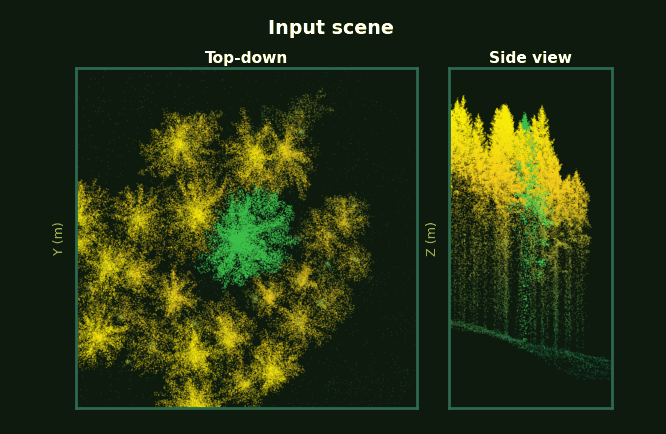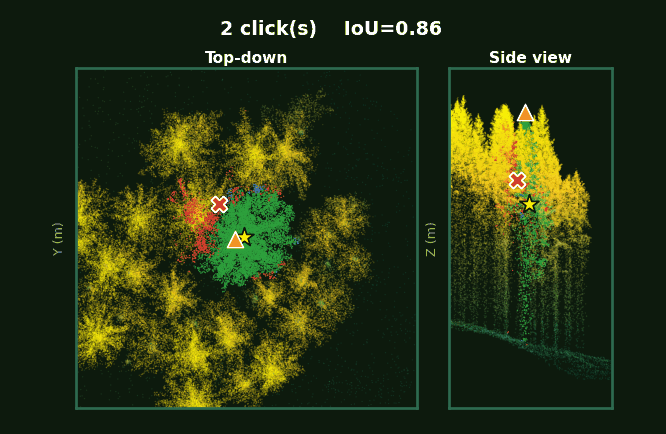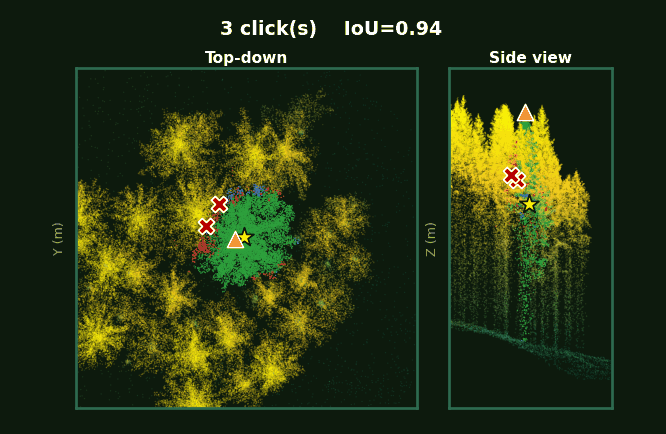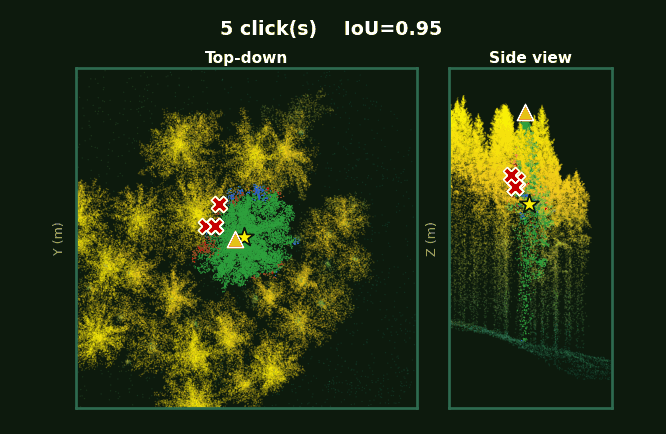
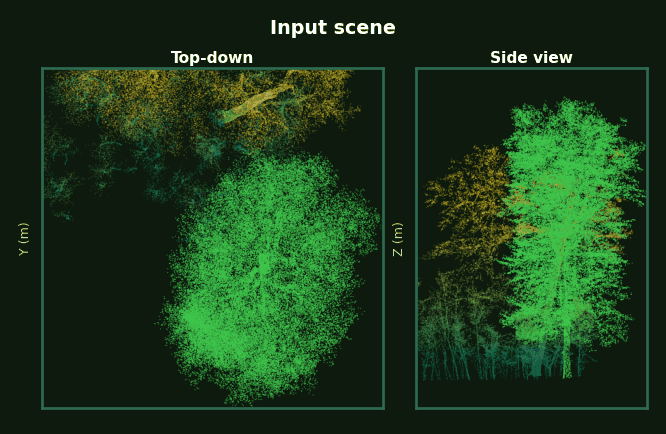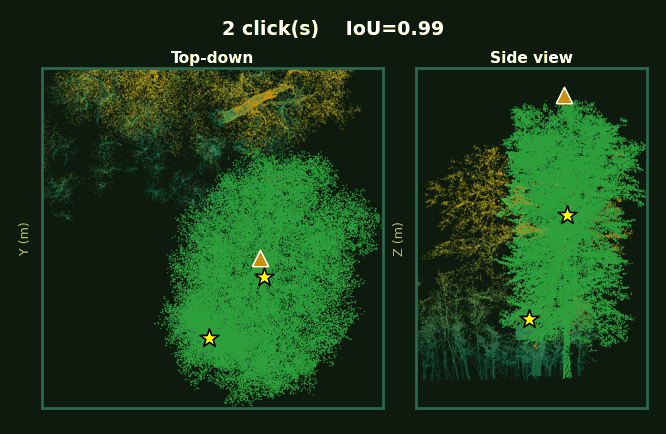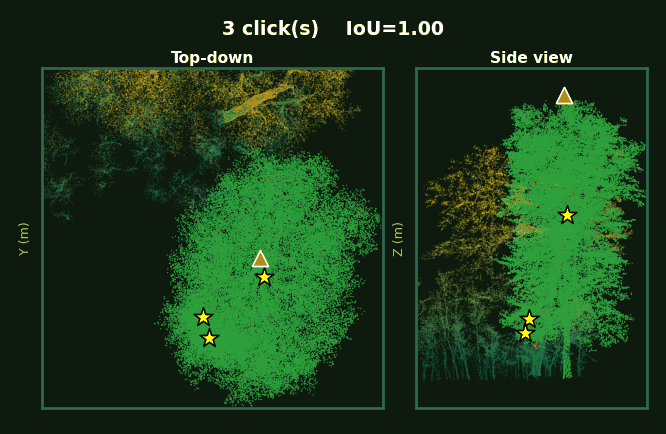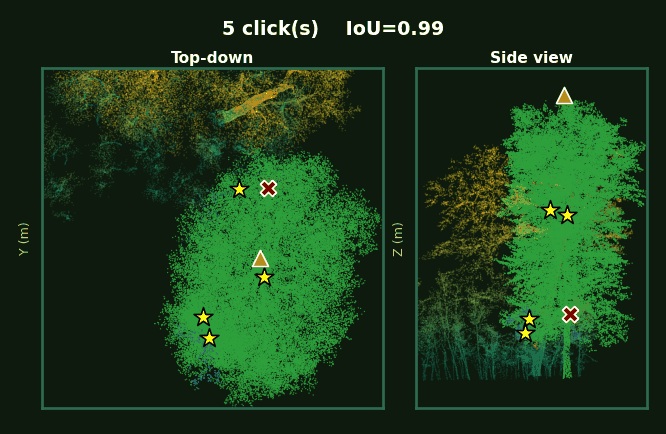
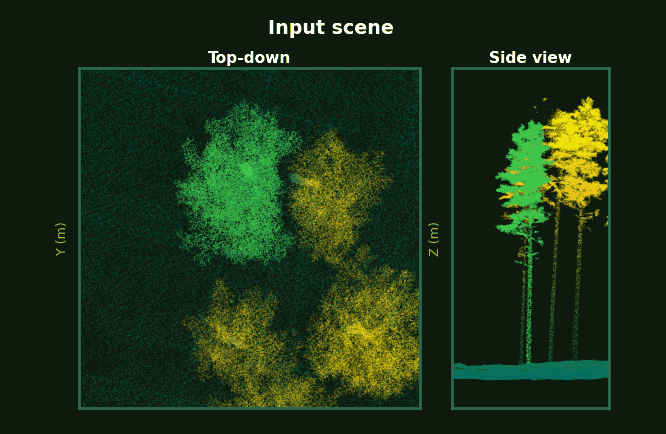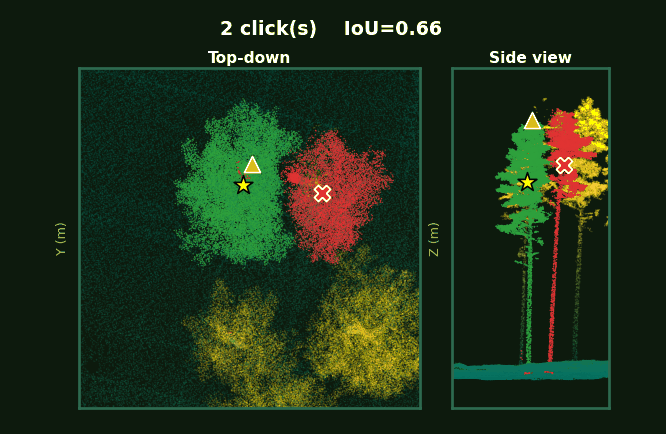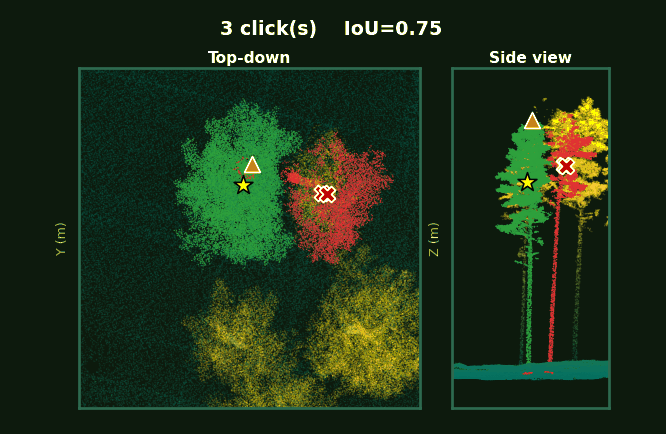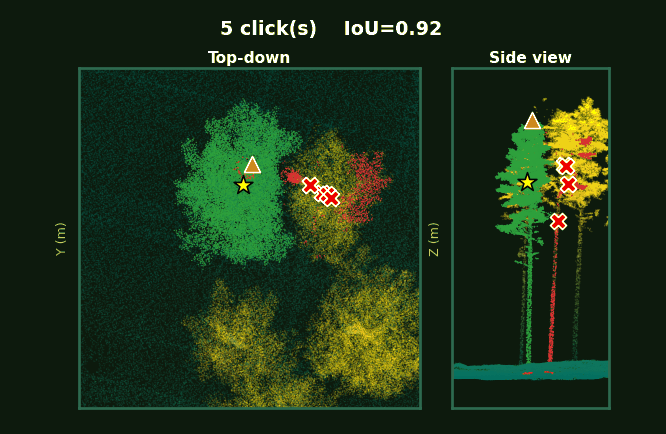
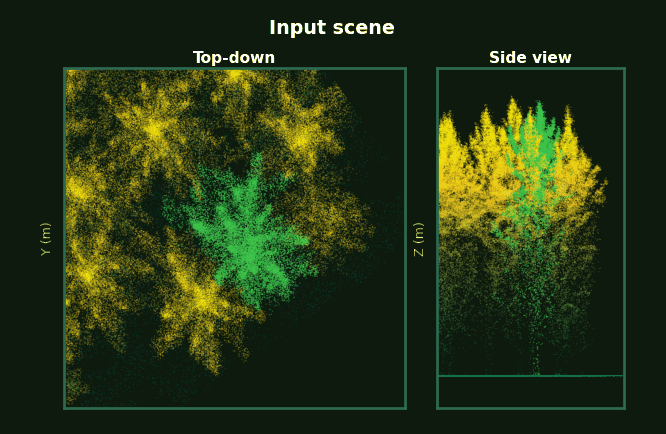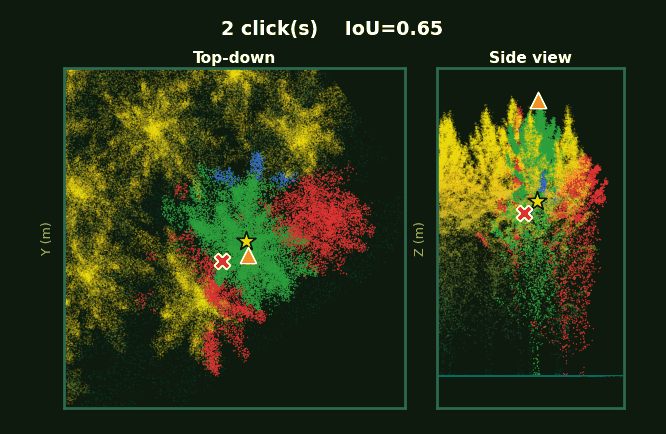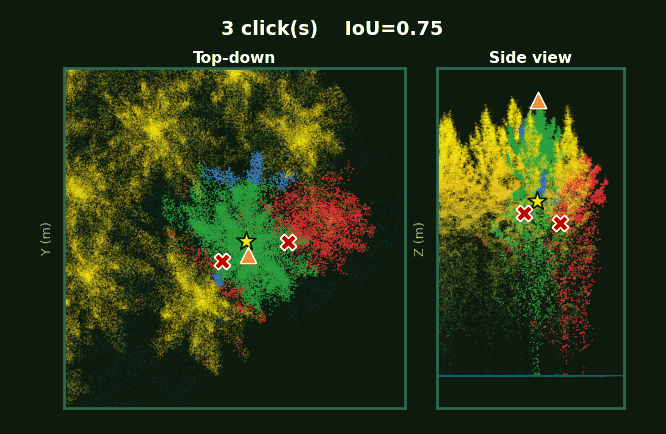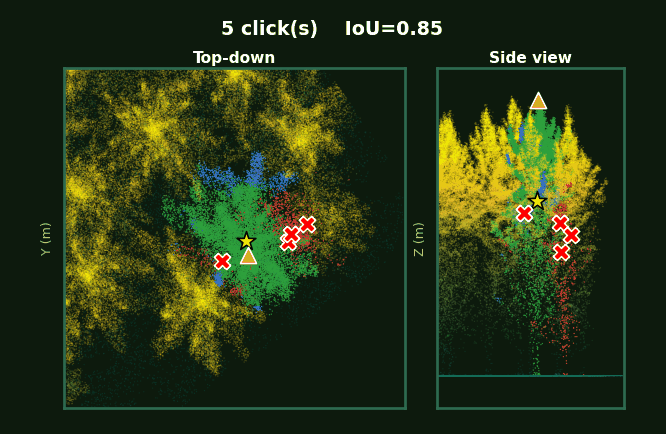
Same scene, same click budget.
Point-SAM
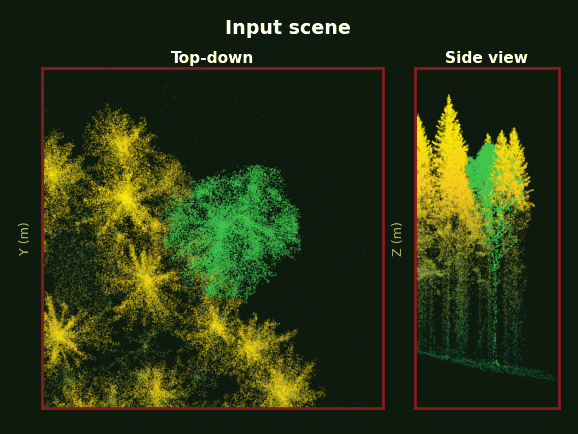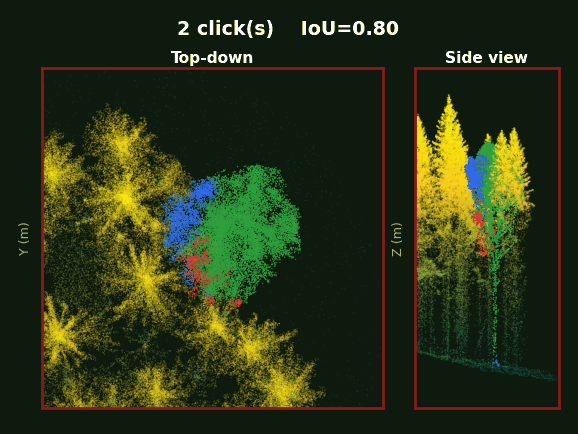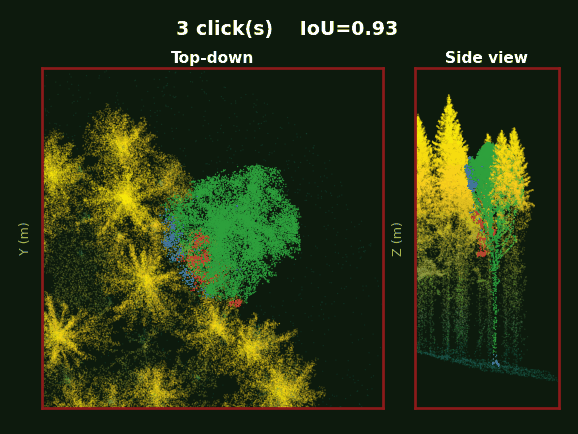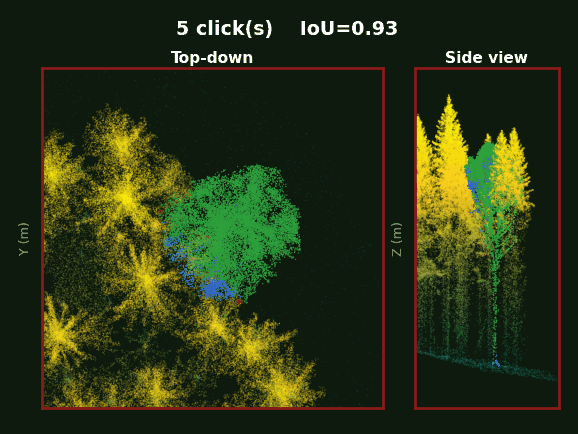
SelectAnyTree Ours
SelectAnyTree turns a structure-aware forest backbone into a promptable instance segmentation model through four stages:
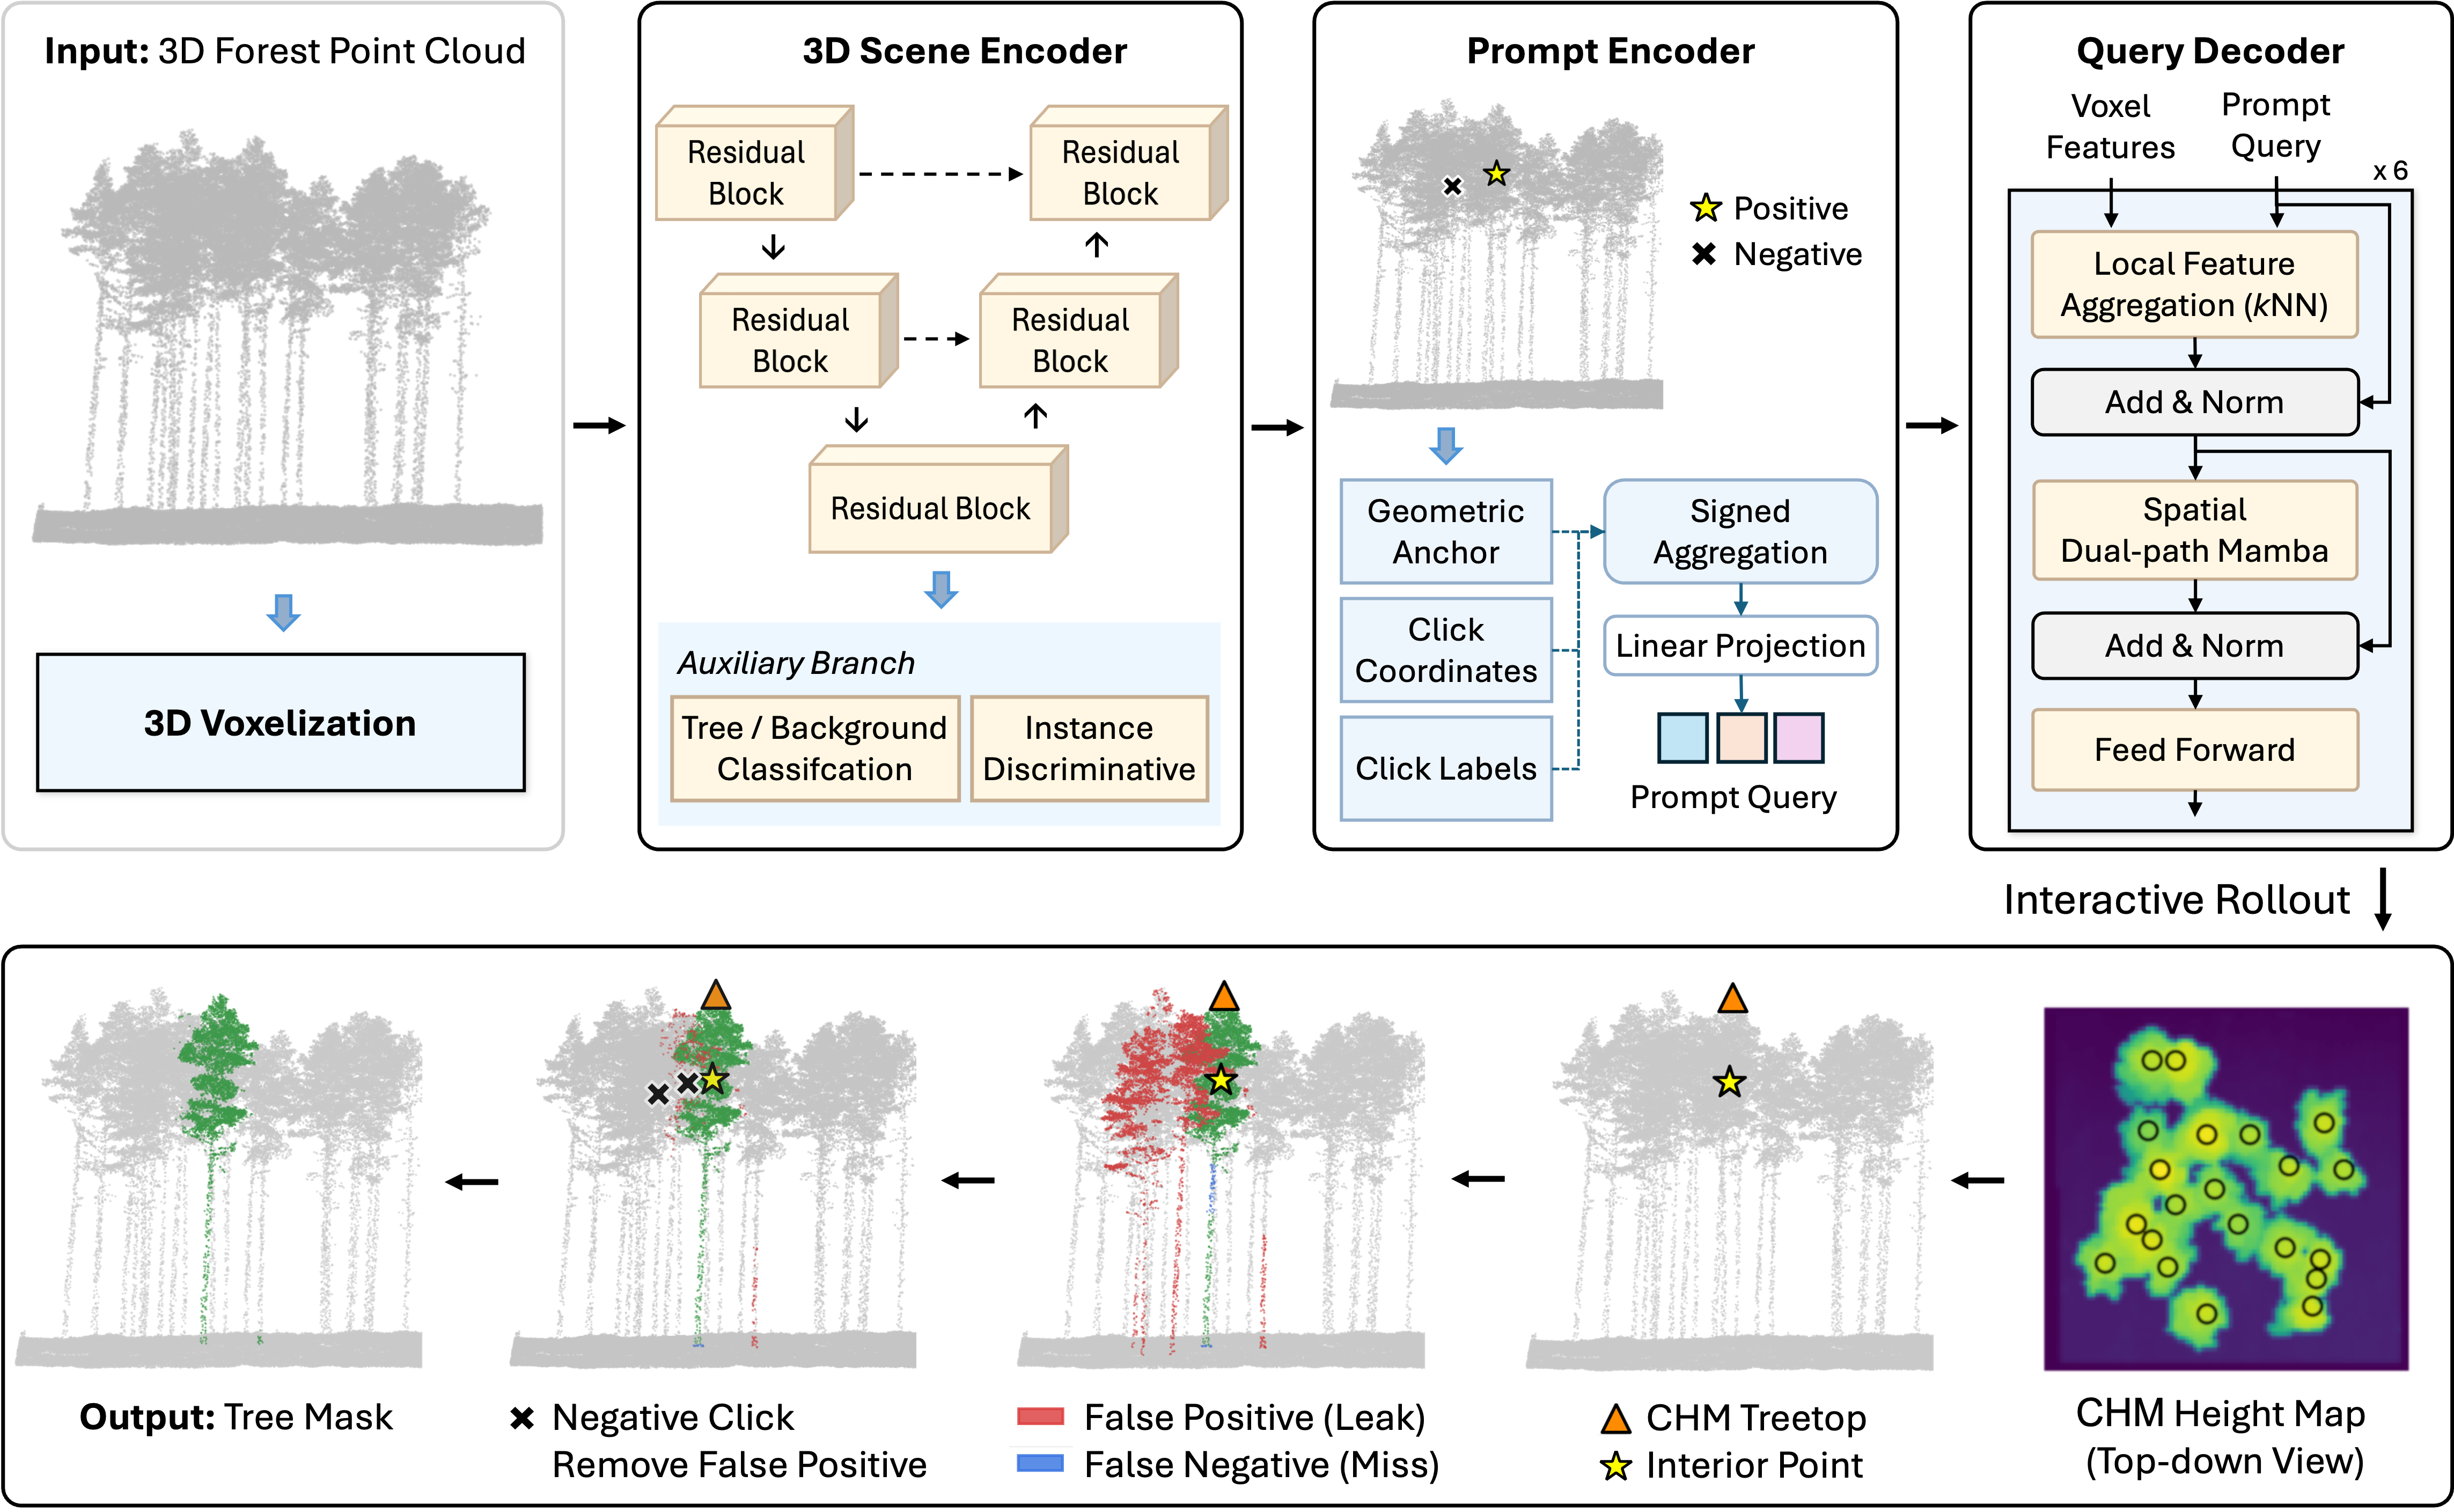
SelectAnyTree architecture. Scene encoding is performed once per plot; prompt encoding and decoding are repeated per click set.
FOR-instanceV2 test set (in-distribution) and LAUTx (cross-dataset generalization, held-out). Bold = best, underline = second best.
GPU wall-clock time (ms) per scene for a k-click session on the FOR-instanceV2 test set.
Single-click segmentation compared against promptable baselines on the same target tree.
@article{nguyen2026selectanytree,
  title   = {SelectAnyTree: A Promptable Instance Segmentation Model for 3D Forest {LiDAR} Point Clouds},
  author  = {Nguyen, Trung Thanh and Lusk, Daniel and Gerberding, Kilian and Vajna-Jehle, Janusch and Vu, Tuan-Anh and Le, Duc Viet and Vo, Tu and Nguyen, Phi Le and Kawanishi, Yasutomo and Komamizu, Takahiro and Ide, Ichiro and Frey, Julian and Kattenborn, Teja},
  journal = {arXiv preprint arXiv:2606.27491},
  year    = {2026}
}